Question 261 · 370 in bank
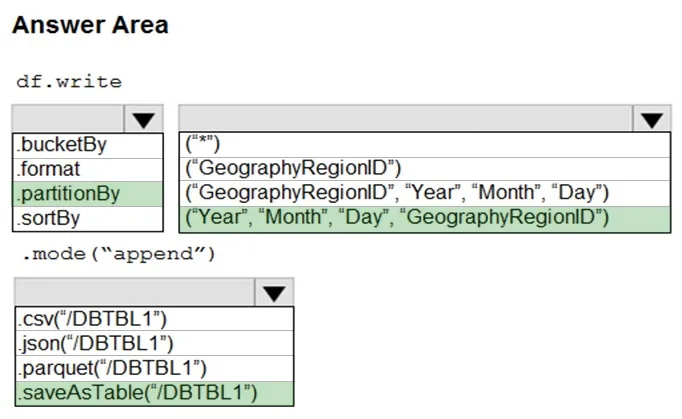
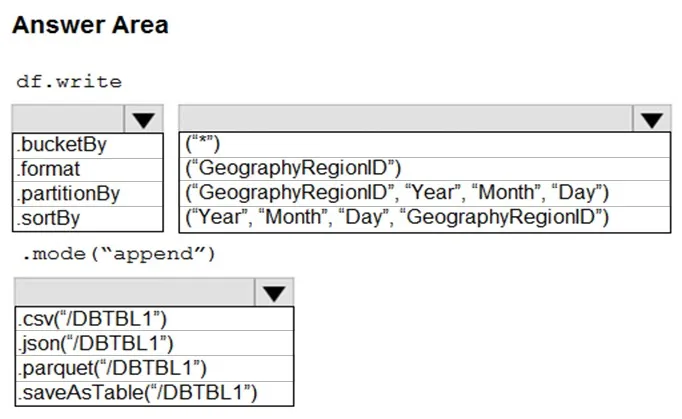
HOTSPOT - You develop a dataset named DBTBL1 by using Azure Databricks. DBTBL1 contains the following columns: ✑ SensorTypeID ✑ GeographyRegionID ✑ Year ✑ Month ✑ Day ✑ Hour ✑ Minute ✑ Temperature ✑ WindSpeed ✑ Other You need to store the data to support daily incremental load pipelines that vary for each GeographyRegionID. The solution must minimize storage costs. How should you complete the code? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point. Hot Area:
This is an interactive task on the real exam — a drag-and-drop, hotspot or ordering question. There is nothing to select here, so the answer is shown below for reference.
Show the answer figure
Answer: See figure below
Explanation
Box 1: .partitionBy - Incorrect Answers: ✑ .format: Method: format(): Arguments: "parquet", "csv", "txt", "json", "jdbc", "orc", "avro", etc. ✑ .bucketBy: Method: bucketBy() Arguments: (numBuckets, col, col..., coln) The number of buckets and names of columns to bucket by. Uses Hive's bucketing scheme on a filesystem. Box 2: ("Year", "Month", "Day","GeographyRegionID") Specify the columns on which to do the partition. Use the date columns followed by the GeographyRegionID column. Box 3: .saveAsTable("/DBTBL1") Method: saveAsTable() Argument: "table_name" The table to save to. Reference: https://www.oreilly.com/library/view/learning-spark-2nd/9781492050032/ch04.html https://docs.microsoft.com/en-us/azure/databricks/delta/delta-batch
Source: Adapted from community discussion — PallaviPatel
References