Question 241 · 354 in bank
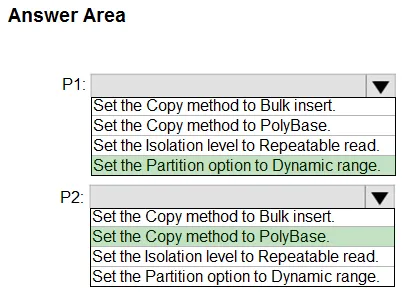
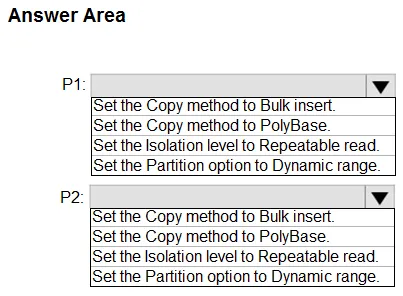
HOTSPOT - You have an Azure Data Factory instance named ADF1 and two Azure Synapse Analytics workspaces named WS1 and WS2. ADF1 contains the following pipelines: ✑ P1: Uses a copy activity to copy data from a nonpartitioned table in a dedicated SQL pool of WS1 to an Azure Data Lake Storage Gen2 account ✑ P2: Uses a copy activity to copy data from text-delimited files in an Azure Data Lake Storage Gen2 account to a nonpartitioned table in a dedicated SQL pool of WS2 You need to configure P1 and P2 to maximize parallelism and performance. Which dataset settings should you configure for the copy activity of each pipeline? To answer, select the appropriate options in the answer area. Hot Area:
This is an interactive task on the real exam — a drag-and-drop, hotspot or ordering question. There is nothing to select here, so the answer is shown below for reference.
Show the answer figure
Answer: See figure below
Explanation
P1: Set the Partition option to Dynamic Range. The SQL Server connector in copy activity provides built-in data partitioning to copy data in parallel. P2: Set the Copy method to PolyBase Polybase is the most efficient way to move data into Azure Synapse Analytics. Use the staging blob feature to achieve high load speeds from all types of data stores, including Azure Blob storage and Data Lake Store. (Polybase supports Azure Blob storage and Azure Data Lake Store by default.) Reference: https://docs.microsoft.com/en-us/azure/data-factory/connector-azure-sql-data-warehouse https://docs.microsoft.com/en-us/azure/data-factory/load-azure-sql-data-warehouse