Question 71 · 202 in bank
What is the retention of job run history?
Show answer
Answer: C
Databricks Certified Data Engineer Professional202 questions across 21 pages are complete and free, with no account or card.
202 questions in this bank
Free access · progress saved on this device
What is the retention of job run history?
Answer: C
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. Which statement describes the contents of the workspace audit logs concerning these events?
Answer: C
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB. Which of the following likely explains these smaller file sizes?
Answer: A
It is important here to understand the difference between the partition size and the data files. the partition size is 1GB which is caused by OPTIMIZE and also expected. In each partition are data files. Databricks did an attuning to these datafile and resized them to a small size to be able to do MERGE statements efficiently that's why A is the correct answer
Source: Adapted from community discussion — Melik3
A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries. In which location can one review the timeline for cluster resizing events?
Answer: D
Its possible to see the metricks of compute with Ganglia, but the question is about a timeline so D, Cluster Event Log seems correct.
Source: Adapted from community discussion — imatheushenrique
When evaluating the Ganglia Metrics for a given cluster with 3 executor nodes, which indicator would signal proper utilization of the VM's resources?
Answer: B
The data engineer is using Spark's MEMORY_ONLY storage level. Which indicators should the data engineer look for in the Spark UI's Storage tab to signal that a cached table is not performing optimally?
Answer: C
*THE CORRECT ANSWER IS: C* PLEASE IGNORE MY PREVIOUS ANSWER. Long story short, B is correct in the context of non-functional requirement, but the question is based in functional requirement, and sorry for the confusion.
Source: Adapted from community discussion — Freyr
Review the following error traceback:
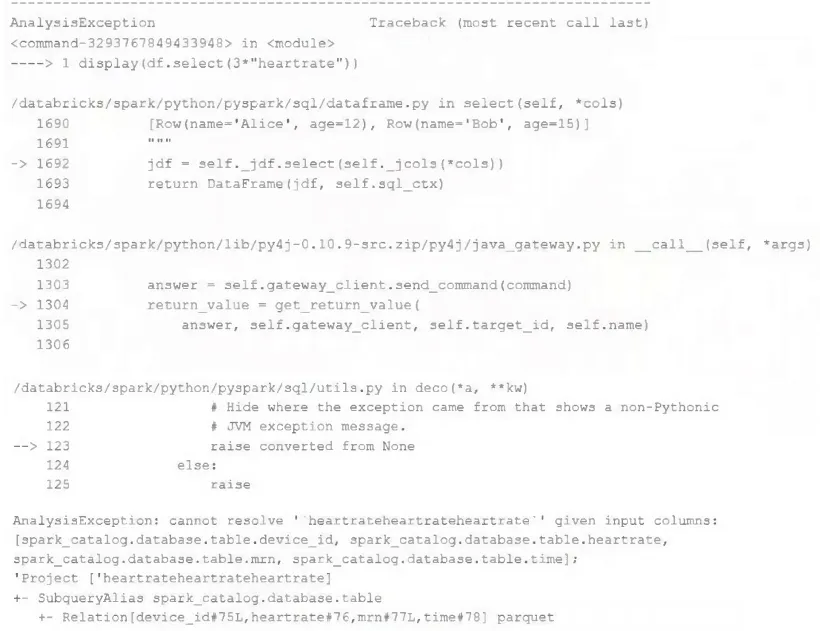
Which statement describes the error being raised?
Answer: B
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
Answer: C
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code. Which benefit offsets this additional effort?
Answer: C
What describes integration testing?
Answer: D
D. It validates interactions between subsystems of your application. An integration test is used for different softwares validation components, subsystems, or applications that has dependencies.
Source: Adapted from community discussion — imatheushenrique
Keyboard:J Kmove between questionsA–Dselect an answerRshow or hide the answer← →change page
DE-PRO practice, question 71. 202 questions available.
Version 1.0.0. How we source questions